Seoyoon Yum and Sehoon Kim · Accepted to the NeurIPS 2026 Workshop on On-Device Intelligence
Paper · PDF · Code and experiments
Problem
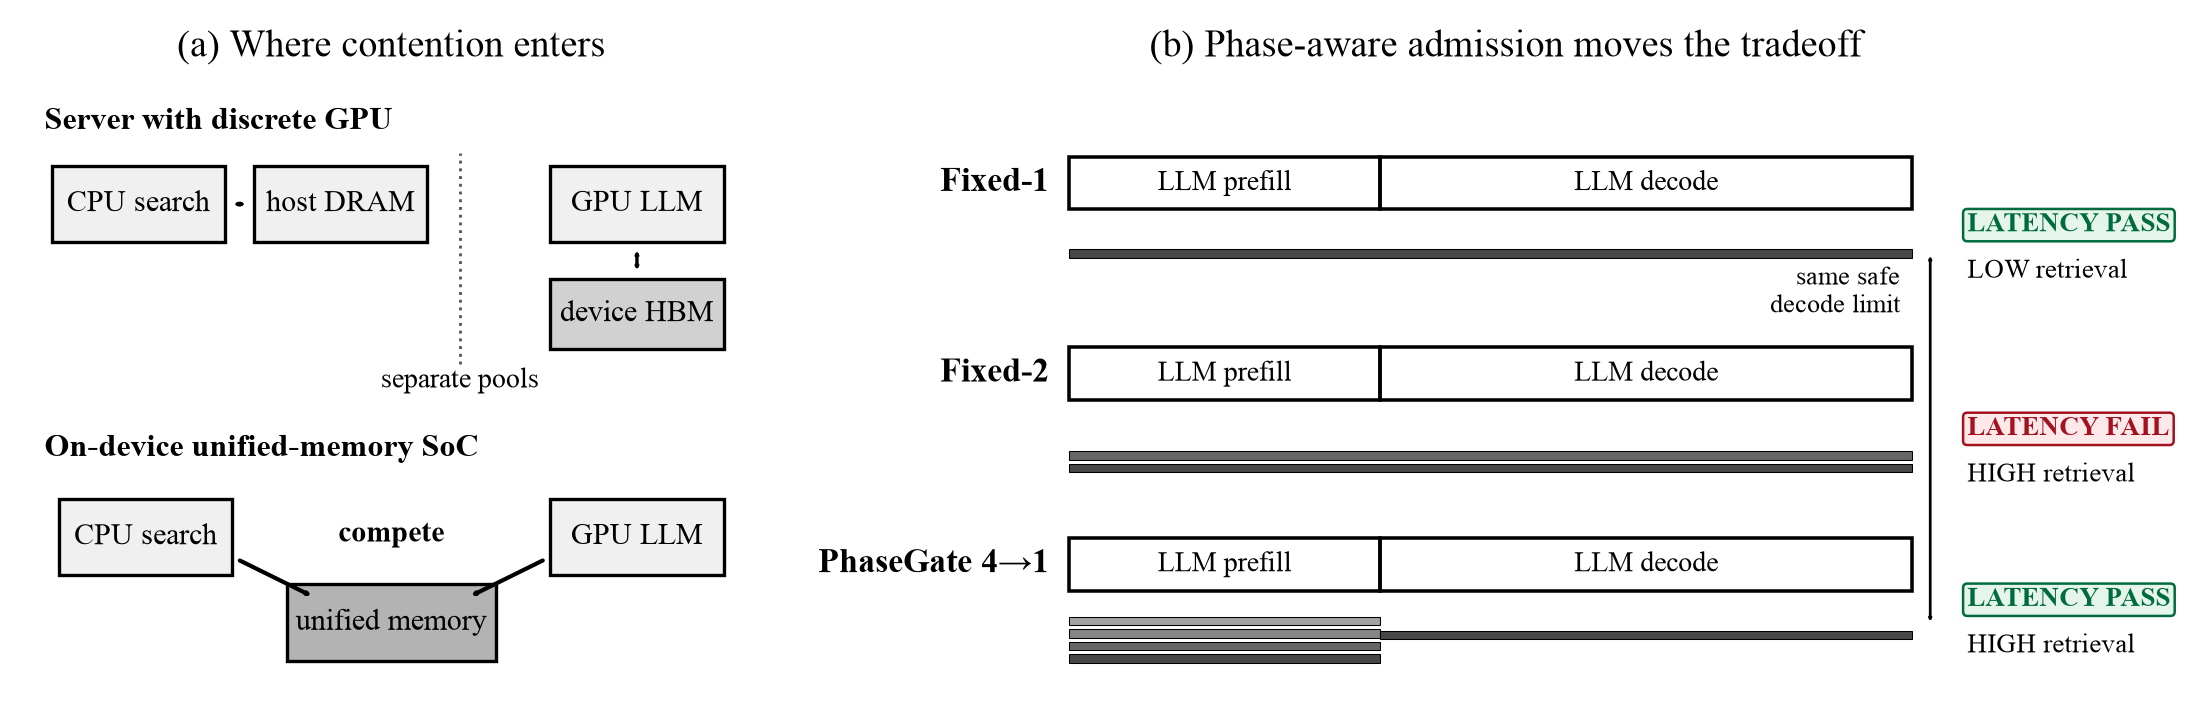
Retrieval and LLM inference compete for shared resources, making it difficult to improve throughput while keeping response latency low.
Contribution
Initiated and led the research; co-authored the paper with Prof. Sehoon Kim (KAIST). Built a resource scheduler that adapts retrieval activity to the demands of LLM inference.
Result
In controlled experiments, PhaseGate achieved 2.0× retrieval throughput over a fixed scheduling baseline under the same latency constraint.